

About Our Contributing Expert
Dr. Sebastian Wernicke | Partner at Oxera, Author of Data Inspired, TED Speaker
Dr. Sebastian Wernicke is a data and AI transformation leader, Partner at Oxera, bestselling author of Data Inspired, and a three-time TED speaker. Previously, he served as Chief Data Scientist at One Data and Head of Data Science at Solon, where he built and scaled industry-leading data science organisations and delivered over 100 AI and data-driven transformation projects. Today, he helps organisations combine data, AI, and organisational culture to make better decisions, drive innovation, and create lasting business value.
Known for his human-centric approach, Sebastian challenges organisations to move beyond being merely data-driven toward becoming truly data-inspired. His work focuses on combining data, AI, psychology, and organisational culture to improve decision-making, foster innovation, and create lasting business transformation. His TED Talks have reached millions of viewers, and he regularly advises executives on building cultures where curiosity, evidence, and technology work together to unlock breakthrough outcomes. We’re thrilled to feature his insights on Modern Data 101.
We actively collaborate with data experts to bring the best resources to a 20,000+ strong community of data leaders and practitioners. If you have something to share, reach out!
🫴🏻 Share your ideas and work: community@moderndata101.com
*Note: Opinions expressed in contributions are not our own and are only curated by us for broader access and discussion. All submissions are vetted for quality & relevance. We keep it information-first and do not support any promotions, paid or otherwise!
Let’s Dive In
When a company walks me through its data quality program, I inevitably ask a question guaranteed to cause irritation:
“Which decisions have actually gotten better as a result of this, and how much is that improvement worth?”
The answer is rarely specific. Instead, a slow realization settles over the room: it hadn’t occurred to anyone to track this systematically.
The irritation is particularly sharp when the scorecard is immaculate, boasting high data completeness and datasets firmly inside their freshness windows. Because better data is always good, right?
Real data resists a neat number
Run down the dimensions of almost any data quality program today, and you will notice they share a single feature: every metric is assessed the moment data is produced.
None capture what happens after it leaves the warehouse. The obvious explanation is ease. Dimensions measured before use are simple to track.
Completeness is a ratio and freshness is a gap between two timestamps. The value a dataset creates, however, emerges slowly, tangled in human judgment, and resists a neat number.
A deeper reason is that measuring decision value is dangerous in a way completeness never is. It might reveal that the business is failing to capitalize on an expensive, immaculately governed data estate. No department is in a hurry to commission a metric that indicts its own habits.
Data adoption is as important as data quality
Consequently, we mistake the metrics we track for the entirety of data value. Data professionals often defend this boundary, arguing their job is to deliver reliable data, not force the business to use it.
While understandable, this defense misses the gulf between “forcing” use and “understanding relevance.” The result is a peculiar kind of blindness. A dataset can pass every check on the scorecard and still feed a report that no one reads. It can inform a high-stakes decision or fail to.
In my book Data Inspired, I describe this as a failure to examine an organization’s decision framework. Treating data in isolation misses its core economic purpose: changing decisions for the better.
Setting aside regulatory mandates or genuine option value, data that informs no choice has no financial justification for staying active. Keep unstructured sandboxes open for raw exploration, but apply a strict decision-test before promoting anything to an expensive production pipeline. Maintaining unused data burns cloud compute and engineering hours, a shadow cost that proper lifecycle management and archiving would eliminate.
This is not to say traditional quality metrics are vanity projects
You cannot build a winning strategy on a foundation of chaos. Bad data reliably produces bad decisions, making master data management and system consolidation true prerequisites.
High-integrity data, on the other hand, is load-bearing: remove it and the structure collapses.
The trouble is mistaking the foundation for the finished building. After all, nobody congratulates a restaurant for sourcing world-class, fresh ingredients without ever asking whether the final meal tasted good.
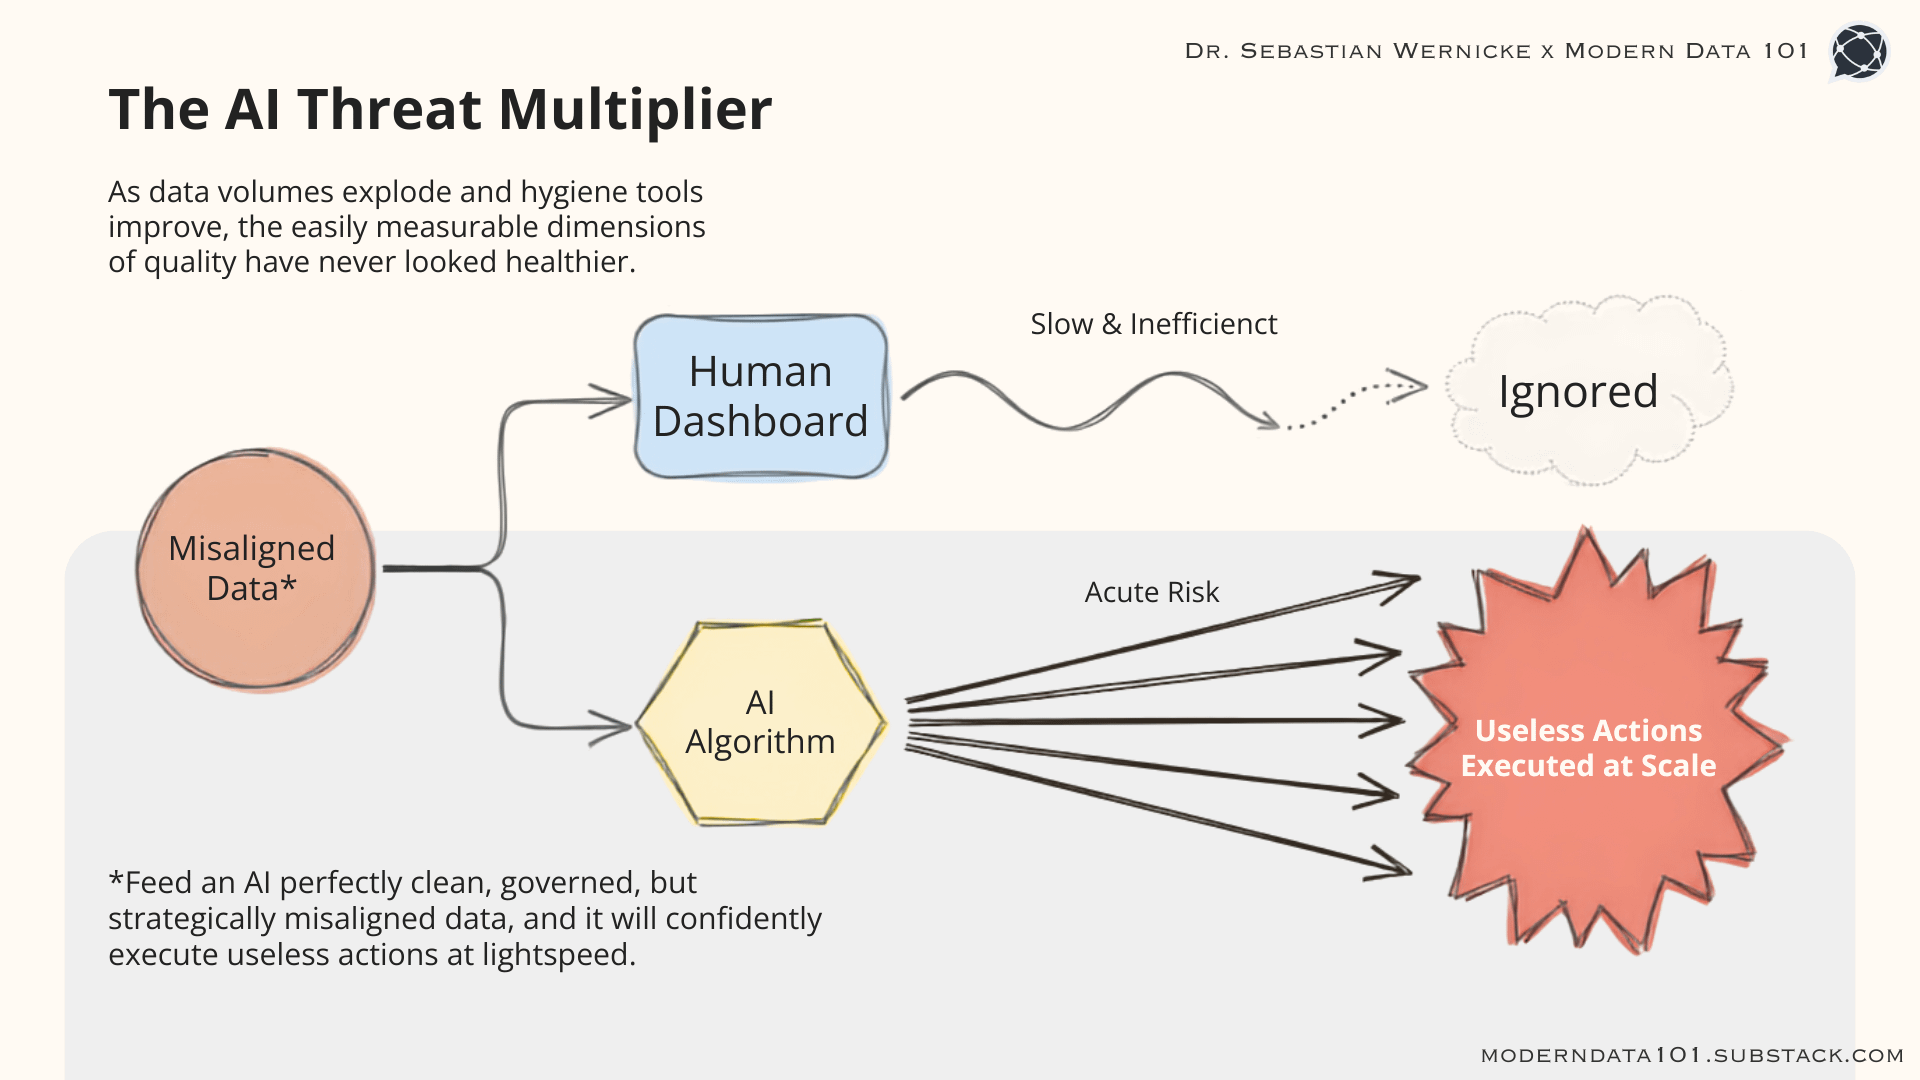
The rise of AI exacerbates this disconnect, turning a chronic inefficiency into an acute risk. As data volumes explode and hygiene tools improve, the easily measurable dimensions of quality have never looked healthier.
But we are no longer just feeding passive dashboards. We are feeding algorithms that automate actions at scale. If you feed an AI completely clean, perfectly governed, but strategically misaligned data, it will confidently execute useless actions at lightspeed.
Decision value is undeniably hard to measure
Outcomes are noisy. A sound decision can end badly, and a poor one can get lucky. But this inherent complexity does not justify measuring nothing.
Look at marketing attribution. It is notoriously noisy, yet no marketing team is permitted to grade itself solely on the volume of ads produced. They are forced to build proxy metrics for revenue impact.
Data teams must be held to the same standard. Granted, they often hide behind hygiene because they get blamed for bad outcomes but rarely credited for wins. The fix is co-ownership: they shouldn’t own the final decision, just the metric tracking whether the data was actually relevant to it.
If you own a data quality framework, add a dimension for decision value, however crude that first iteration might be.
You can start coarsely with a blunt, but deeply revealing proxy question: Before a decision is made, how often does anyone look at the data and change their mind?
In many organizations, the honest answer is “rarely.” That fact alone should reshape priorities. From there, we can compare decisions made with data against those made without it. This approach rarely produces a clean, binary answer, but it vastly outperforms a scorecard that stays silent on a question worth asking.
Fixing the issue of not measuring decision quality in the long run requires a concrete shift in practice: working backward from the decision rather than forward from the dataset.
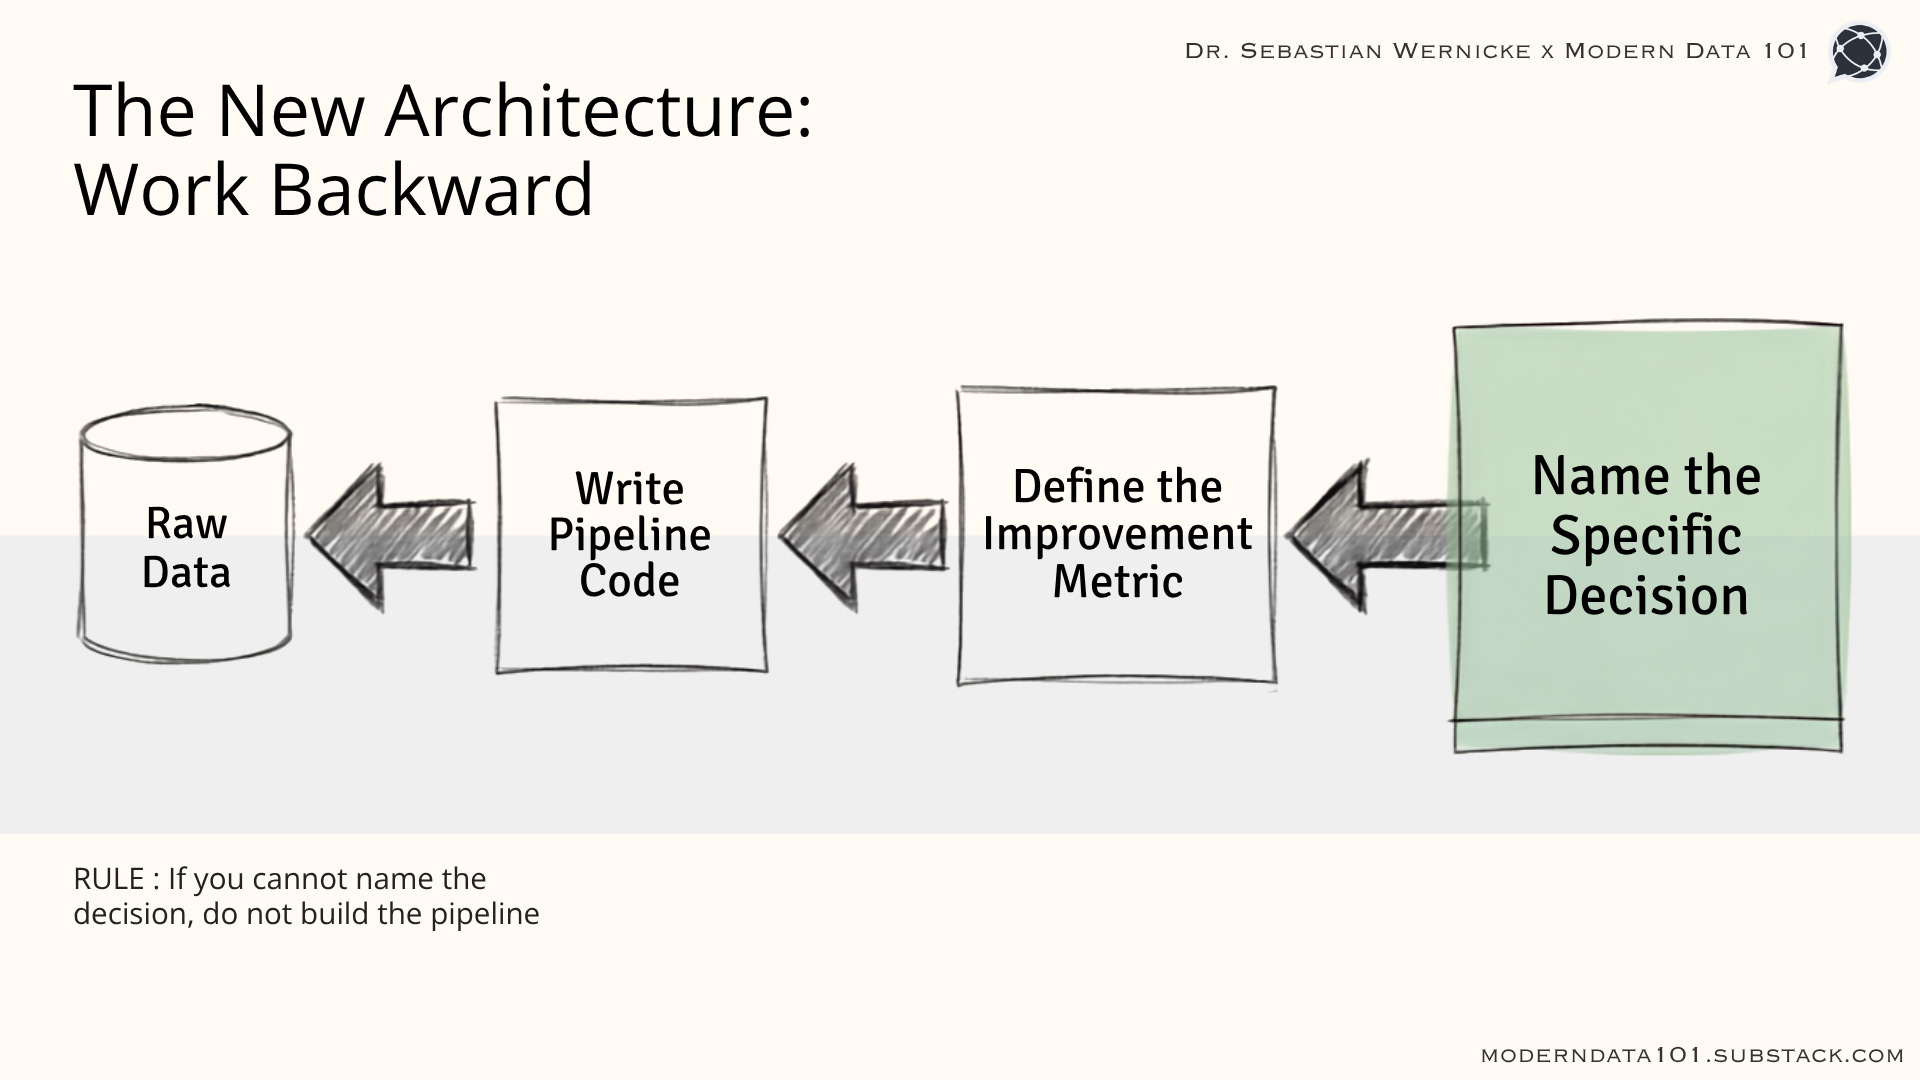
If you write data product specifications, name the specific decisions the product exists to improve (not in theory, but in reality). Define how you will measure that improvement before writing a single line of pipeline code.
If you cannot name the decision, do not build the pipeline. If you sit on a governance board, refuse to view the job as complete based on hygiene alone. Ask what decision is now better because this data exists.
Finally, if you are an executive funding this infrastructure and wondering why cleaner data isn’t producing better results, know that you are asking the exact right question.
We have built an entire discipline around measuring data quality. What we must not forget is that the part that is hard to count (whether any of this leads to a better decision) was always the entire point.
MD101 Support ☎️
If you have any queries about the piece, feel free to connect with the author(s). Or connect with the MD101 team directly at community@moderndata101.com 🧡
Author Connect 💬
Got questions or want to share your own experiments? Find Dr. Wernicke on LinkedIn or drop a comment below. 💬
More from Dr. Sebastian Wernicke
From the MD101 team 🧡
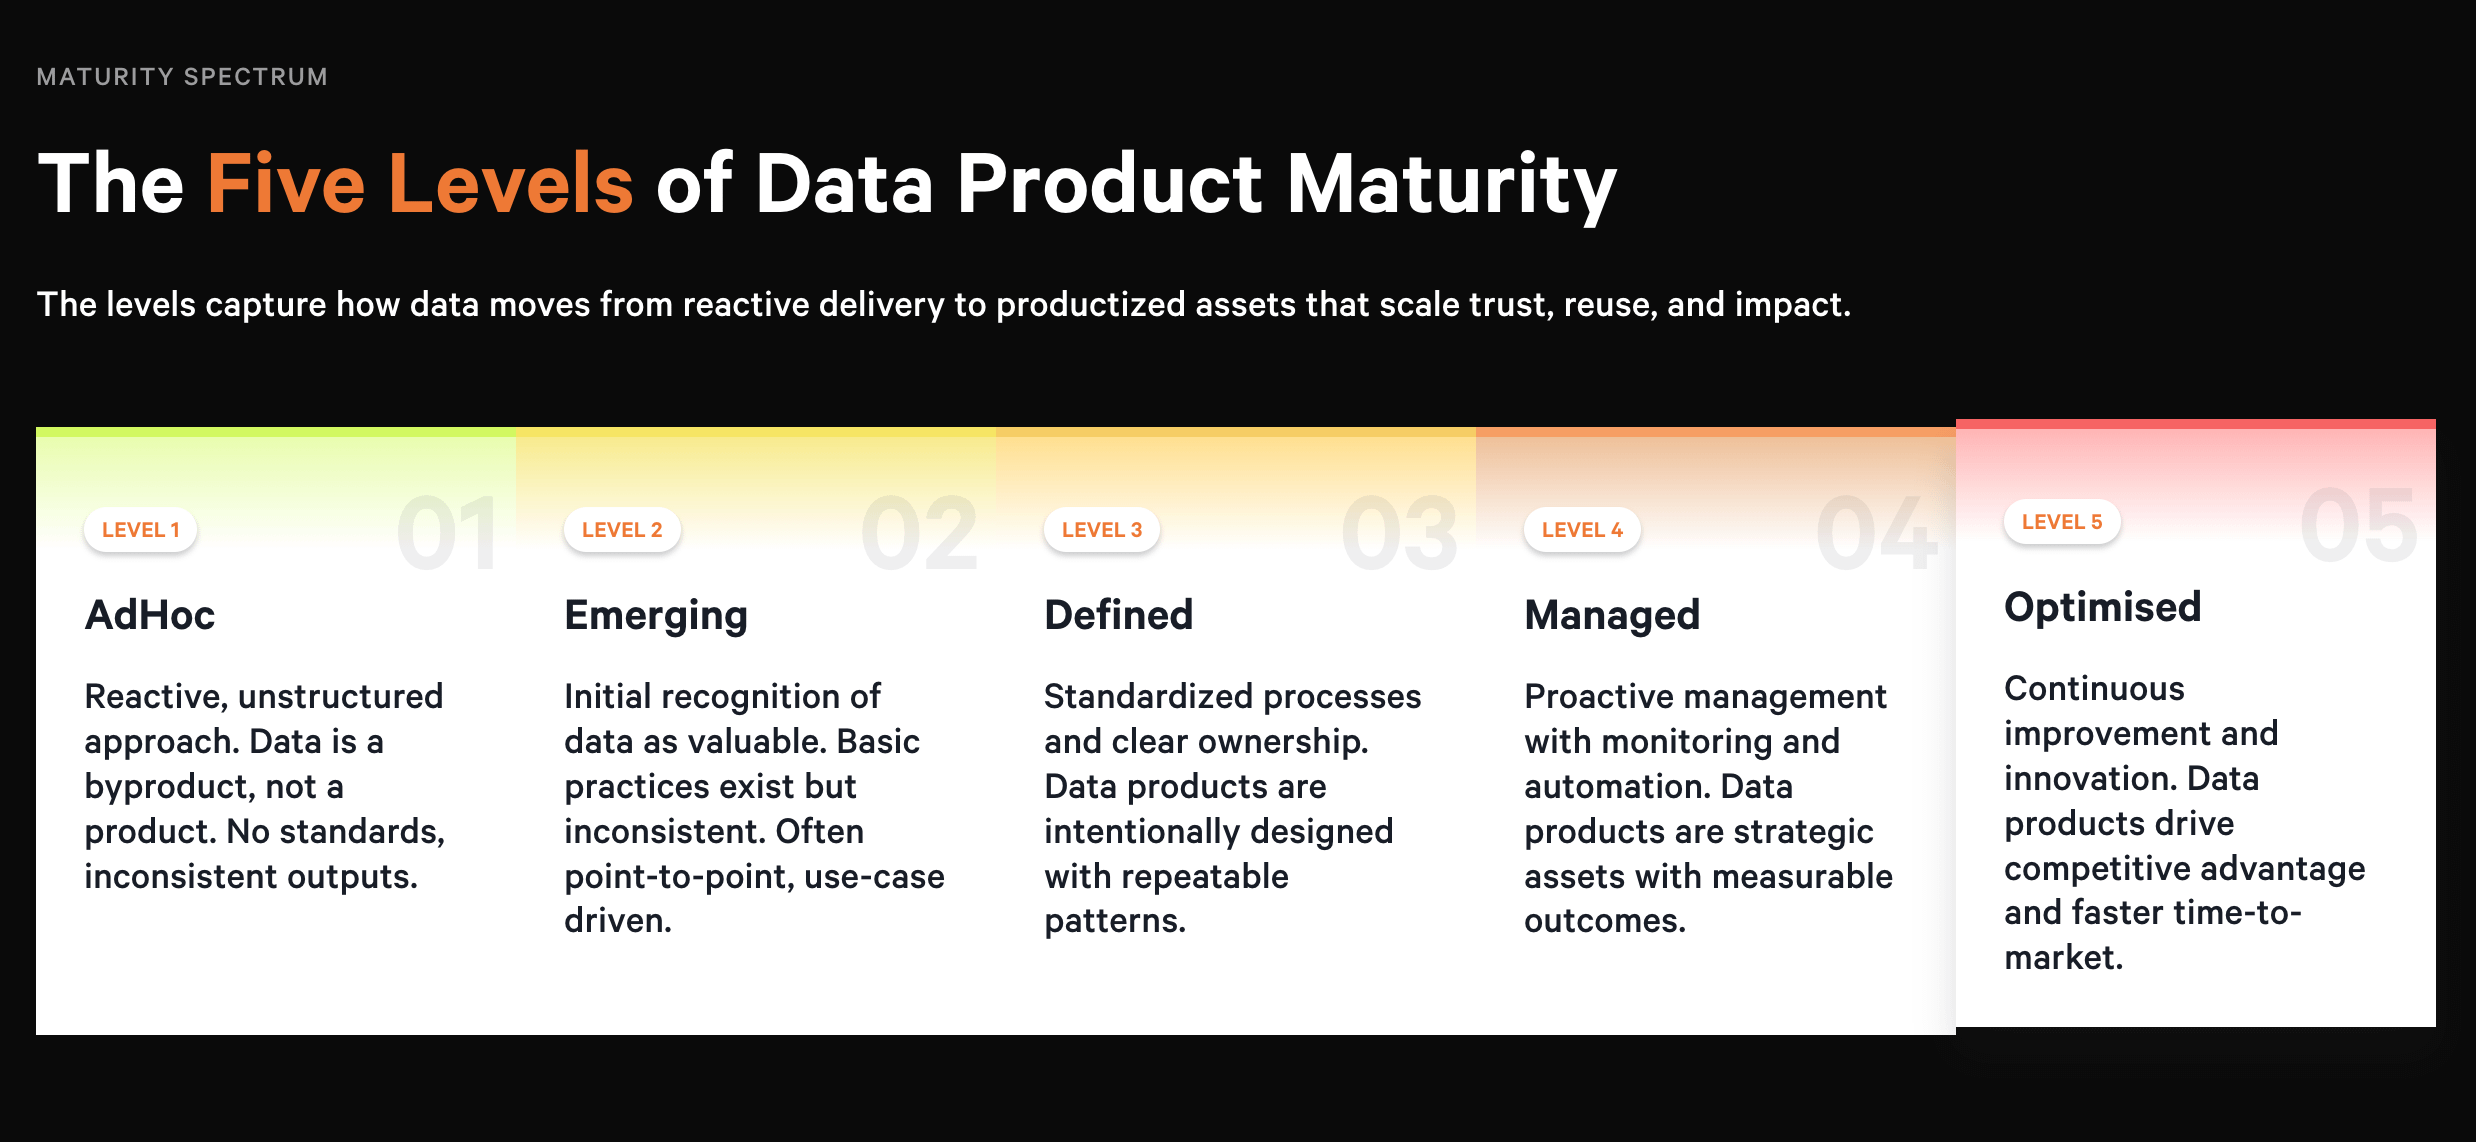
🧪 Data Product Maturity Assessment Tool
The Data Product Maturity Assessment was built on proven and recognised frameworks of DATSIS from Data Mesh architecture and VAULTIS from the US DoD Data Strategy. It evaluates your data products across nine dimensions.
From ownership and discoverability to SLAs, reusability, and value delivery. The result is a maturity fingerprint: a clear, framework-backed view of where your organisation stands, and where to focus next. Take yours →

Well said. I'll add, in the spirit of Thaler and Sunstein's "Nudge," that decisions repeat. Finding the right decision to model is a key part of your approach. Thank you for this clear, helpful piece!
ZH
Thanks for this. The restaurant line does the whole argument in one image.
The same substitution happens one level up: organizations measure whether the AI tool got deployed, not whether it changed a decision. A survey of 6,000 executives found 80 percent report no measurable productivity gain despite the investment, which is your report no one reads, scaled to the whole AI stack.
Your fix (name the decision before you build the pipeline) is the same discipline missing a layer up: almost nobody’s chartered to own whether adoption changed an outcome, only whether it happened.